reference · Performance & testing
Correlation and Covariance: Compare Aligned Return Series
Covariance summarizes how two variables move around their means together. Correlation standardizes that relationship by their standard deviations, making the resulting linear-association measure dimensionless.
Key points
- Use aligned paired observations with consistent return definitions.
- Covariance depends on units; correlation normalizes their scale.
- Zero correlation does not prove independence, and high correlation does not guarantee a hedge.
- Rolling estimates depend on the declared window and complete paired observations.
Scope and assumptions
- All return rows and weights are synthetic examples, not observed markets or accounts.
- The main matrix uses the same four complete observations, percentage-point return units and sample divisor n minus 1.
- The pairwise counterexample is a separate dataset; no complete three-series observations exist.
- The downloads are manual research records; no allocation optimization, execution or forward risk guarantee is supplied.
- The rolling-return fixture requires full contiguous three- or five-row pairs; it is too small to establish a stable association or hedge.
- The normal and stress labels are fixed six-observation blocks in an invented twelve-row ledger, not observed crisis classifications or rows selected from market data.
- The six-pair conditional correlations and joint-loss counts are arithmetic only; no causal contagion, diversification guarantee, product result or allocation advice is inferred.
Align the observations before comparing the numbers
Covariance records joint variation in the product of the input units. Pearson correlation divides that covariance by the two standard deviations, so its units cancel. Neither calculation repairs misaligned observations. First fix the return interval, valuation timestamp, account currency, cash-flow treatment and missing-value policy. Comparing a source account's Monday return with a follower's Tuesday return is a different question from comparing the same interval.
Use returns consistently rather than mixing prices, account balances and returns. A deposit is not investment performance. If two account series use different currency conversions, stale marks or fee treatments, preserve those differences before interpreting their similarity as copying accuracy. This page's small datasets are invented mathematical examples, not observed accounts, strategy results or recommended allocations.
Start with the two-series calculation
For paired observations, sample covariance is the sum of products of deviations from each series mean, divided by n − 1. Pearson correlation is that covariance divided by the product of the sample standard deviations. NIST's covariance-matrix definition places variances on the diagonal and pairwise covariances in the other cells.
Take A = −1, 0, +1 and B = −2, 0, +2 in percentage-point return units. Both means are zero. The cross-products sum to 4, so sample covariance is 4 ÷ 2 = 2 squared percentage points. Standard deviations are 1 and 2; correlation is 2 ÷ (1 × 2) = 1. Perfect correlation does not mean equal return sizes.
Converting both inputs to decimals divides covariance by 10,000: 2 becomes 0.0002. Correlation remains 1. A currency P&L series paired with a percentage return has a different covariance unit again. Record units next to every matrix rather than comparing raw covariance magnitudes from incompatible inputs.
Build one three-series sample with visible exclusions
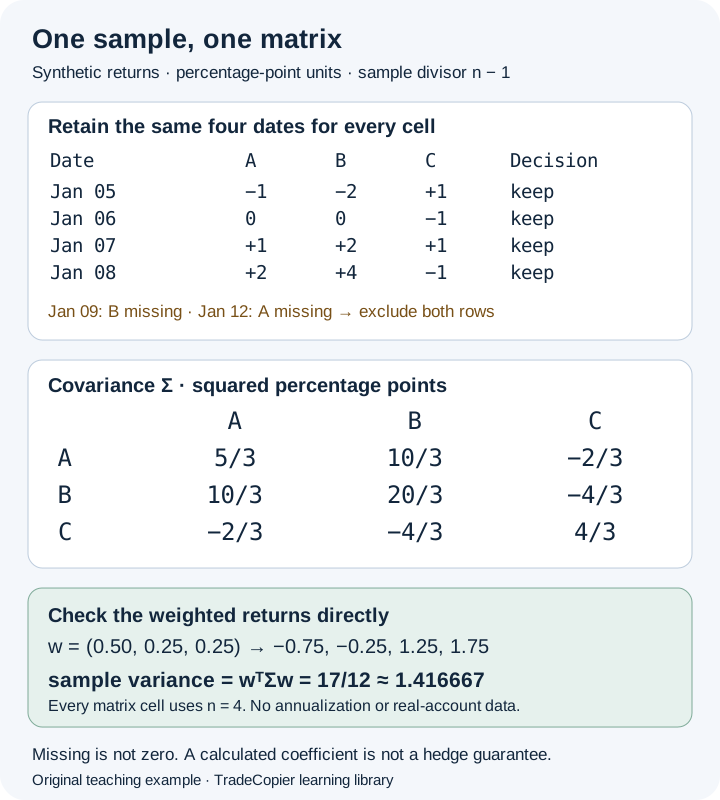
The following fictional daily returns all use percentage-point units, a USD valuation basis and the same 21:00 UTC observation boundary. A value of 1 means a 1% return, not a decimal return of 1. Dates label synthetic observations and do not assert that any particular venue traded. The declared rule is complete-case deletion: include a date only when A, B and C are all observed. A blank is missing, not zero.
| Date in 2026 | A | B | C | Use in matrix? |
|---|---|---|---|---|
| January 5 | −1 | −2 | 1 | Yes |
| January 6 | 0 | 0 | −1 | Yes |
| January 7 | 1 | 2 | 1 | Yes |
| January 8 | 2 | 4 | −1 | Yes |
| January 9 | 3 | Missing | 0 | No: B unavailable |
| January 12 | Missing | 6 | 0 | No: A unavailable |
All nine matrix cells use the same four dates: n = 4 for each diagonal and off-diagonal cell. The retained means are A = 0.5, B = 1 and C = 0. The covariance divisor is 3. Excluded observations remain in the downloadable input record, with the reason for exclusion, so another reader can reproduce the selection.
| Series | A | B | C |
|---|---|---|---|
| A | 5/3 | 10/3 | −2/3 |
| B | 10/3 | 20/3 | −4/3 |
| C | −2/3 | −4/3 | 4/3 |
| Series | A | B | C |
|---|---|---|---|
| A | 1 | 1 | −0.447214 |
| B | 1 | 1 | −0.447214 |
| C | −0.447214 | −0.447214 | 1 |
The exact A–C and B–C correlations are −1/√5. The displayed decimals are rounded; use the fractions and original data for reconciliation. B is exactly twice A here, so this covariance matrix is singular but positive semidefinite. Singularity does not make the covariance calculation invalid; it means the three columns do not supply three independent linear directions.
Reconcile portfolio variance with the actual weighted series
For a fixed linear combination of these same interval returns, let the weights be w = (0.50, 0.25, 0.25). These are illustrative beginning-of-interval fractions of a common capital denominator, held at these values for each modeled interval. They are not contract counts, separate-account margin offsets or an optimized allocation. The hypothetical portfolio return is 0.50A + 0.25B + 0.25C.
The four resulting returns are −0.75, −0.25, 1.25 and 1.75 percentage points. Their mean is 0.50. Their sample variance is (1.5625 + 0.5625 + 0.5625 + 1.5625) ÷ 3 = 17/12, or approximately 1.416667 squared percentage points. Sample standard deviation is approximately 1.190238 percentage points.
The matrix calculation wᵀΣw gives the same 17/12. Include both symmetric off-diagonal terms; counting each covariance only once gives the wrong quadratic expression. Converting returns to decimals gives variance 0.0001416667 and standard deviation 0.01190238. No annualization is applied. Fees, rebalancing costs and financing are absent from this invented series; actual net-return construction must include the chosen treatment consistently.
Why pairwise deletion can produce an unusable matrix
Pairwise deletion keeps a separate available sample for each pair. R's documentation explicitly warns that this can produce a covariance or correlation matrix that is not positive semidefinite. Merely checking that every correlation lies between −1 and 1 is insufficient.
A separate six-row counterexample is included in the download. Its first two rows observe only A and B, moving together; its next two observe only A and C, also together; its final two observe only B and C, moving oppositely. Each off-diagonal correlation therefore uses two observations, while each diagonal uses four. There is no row containing all three values.
| Series | A | B | C |
|---|---|---|---|
| A | 1 (n=4) | 1 (n=2) | 1 (n=2) |
| B | 1 (n=2) | 1 (n=4) | −1 (n=2) |
| C | 1 (n=2) | −1 (n=2) | 1 (n=4) |
This matrix has eigenvalues 2, 2 and −1, and determinant −4. If it were treated as the covariance of standardized variables, the linear combination −A + B + C would have computed variance −3. A variance cannot be negative: the pairwise assembly does not define a valid joint covariance. These are algebraic diagnostics, not simulated portfolio losses.
Do not silently clip the negative result to zero or pass the matrix to an optimizer. Revisit the sample and missingness policy, obtain additional aligned observations, or document a separately justified estimation method. Complete-case deletion solves the common-sample issue in the first example, but can discard information and introduce selection bias when missingness is systematic. It is a declared choice, not a universal recommendation.
How can rolling correlation change with the window?
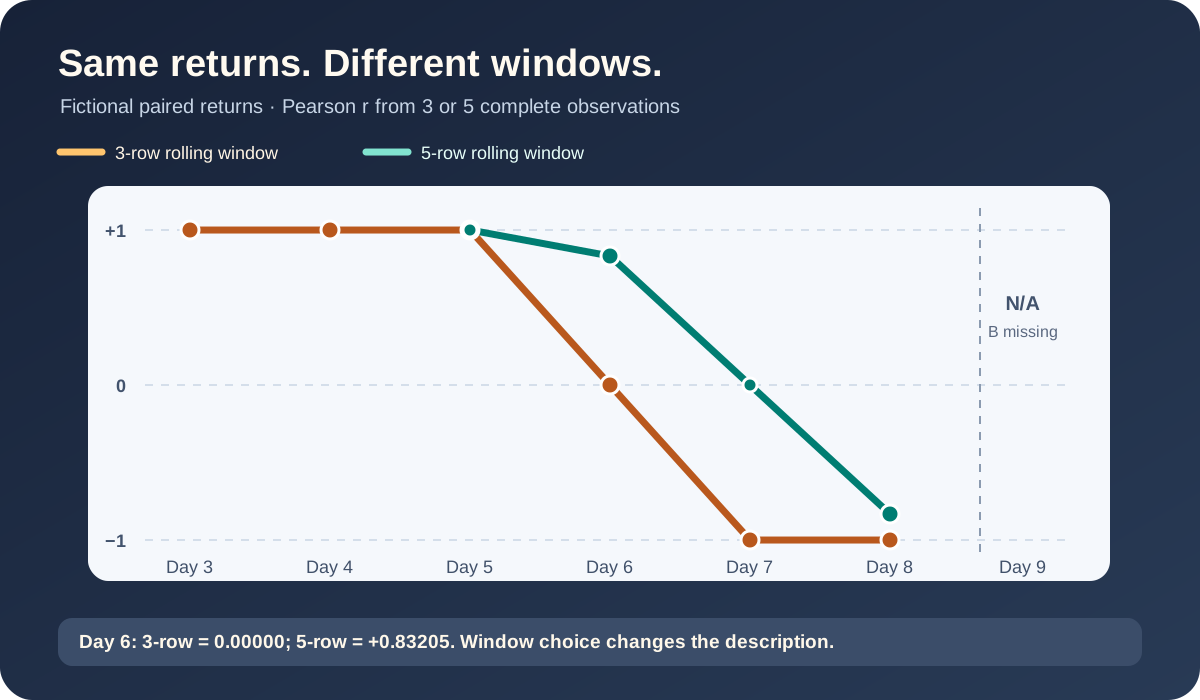
A rolling Pearson correlation recomputes the same formula on a moving block of paired observations. A three-row coefficient and a five-row coefficient can describe the same latest return differently because they include different earlier rows. Neither coefficient predicts the next return, measures copying accuracy or proves that two exposures hedge one another. Record the return definition, clock boundary, window length, valid pair count and missing-value rule before interpreting a line chart.
The next nine rows are fictional, consecutive daily observations in percentage-point return units, with a shared close boundary. The values are not market data or TradeCopier account results. Each right-aligned window includes its ending day and the preceding two or four scheduled days. This example requires all three or five A–B pairs, respectively. Its display minimum of three pairs is an arithmetic rule for this worksheet, not a statistically adequate sample-size recommendation. A two-pair Pearson coefficient would be mechanically +1 or −1 when both series vary, which is especially easy to overread.
| Observation | A return (%) | B return (%) | 3-row r | 5-row r |
|---|---|---|---|---|
| Day 1 | −2 | −2 | Unavailable | Unavailable |
| Day 2 | −1 | −1 | Unavailable | Unavailable |
| Day 3 | 0 | 0 | +1.00000 | Unavailable |
| Day 4 | +1 | +1 | +1.00000 | Unavailable |
| Day 5 | +2 | +2 | +1.00000 | +1.00000 |
| Day 6 | +3 | +1 | 0.00000 | +0.83205 |
| Day 7 | +4 | 0 | −1.00000 | 0.00000 |
| Day 8 | +5 | −1 | −1.00000 | −0.83205 |
| Day 9 | +6 | Missing | Unavailable | Unavailable |
For each complete window, subtract each series' window mean, sum the paired products of deviations, and divide by the square root of the two sums of squared deviations: r = Σ[(A − mean A)(B − mean B)] ÷ √(Σ[A − mean A]² × Σ[B − mean B]²). Using sample covariance and both sample standard deviations yields the same result because their n − 1 divisors cancel. Do not mix a sample covariance with population standard deviations. The coefficient is undefined when either within-window variance is zero.
Day 6 makes the window choice visible. For the three-row window A = (1, 2, 3) and B = (1, 2, 1), the centered cross-product sum is zero, so r = 0. For the five-row window A = (−1, 0, 1, 2, 3) and B = (−1, 0, 1, 2, 1), the centered cross-product sum is 6, the A squared-deviation sum is 10 and the B sum is 5.2. Thus r = 6 ÷ √52 ≈ +0.83205. By Day 8 the respective values are −1 and approximately −0.83205. A five-row display retains earlier positive co-movement longer; it does not make the three-row reversal false.
Day 9 has no observed B return. Both strict contiguous windows include Day 9, so both coefficients are unavailable. Entering zero would invent a return; silently reaching farther back would change the stated window. Pandas documents fixed-window boundaries and minimum periods, and its rolling-correlation reference describes complete-pair and constant-sequence behavior. For this strict fixed-row example, use min_periods=3 or min_periods=5 with the matching window size; a software result is comparable only after matching these choices.
Download the nine-row fictional paired-return CSV to recompute each coefficient. Blank coefficient cells mean the declared full window is unavailable; only an explicit 0.000000 is a calculated zero. Preserve this distinction in a spreadsheet or script.
Successive rolling estimates overlap heavily, so nearby chart points are not independent evidence. A three- or five-observation window is far too small for a stable hedge or strategy conclusion; different intervals, missingness, changing volatility and regime shifts can alter the estimate. Compare several declared windows and the underlying scatter and exception records, then evaluate exposure sizes, contract differences and joint losses separately. This example measures none of those real-world outcomes.
Can diversification shrink during stress? A fixed-window calculation
A single historical correlation is not a promise that two exposures will offset one another in a difficult period. Ang and Bekaert found a higher-volatility equity regime with stronger international co-movement and lower mean returns, while also finding that international diversification retained value in their model. This is evidence that the relationship can depend on state, not a claim that all asset pairs converge or every hedge fails.
Before comparing a quiet block with a stressful one, Forbes and Rigobon and BIS researchers warn that an unadjusted correlation can rise mechanically with volatility even when underlying linkages have not changed. A changed sample coefficient alone therefore does not establish contagion or a new causal mechanism. A February 2026 IMF staff analysis describes a particular stock-bond co-selloff pattern since 2020; it is not a rule for every instrument or copied-account pair.
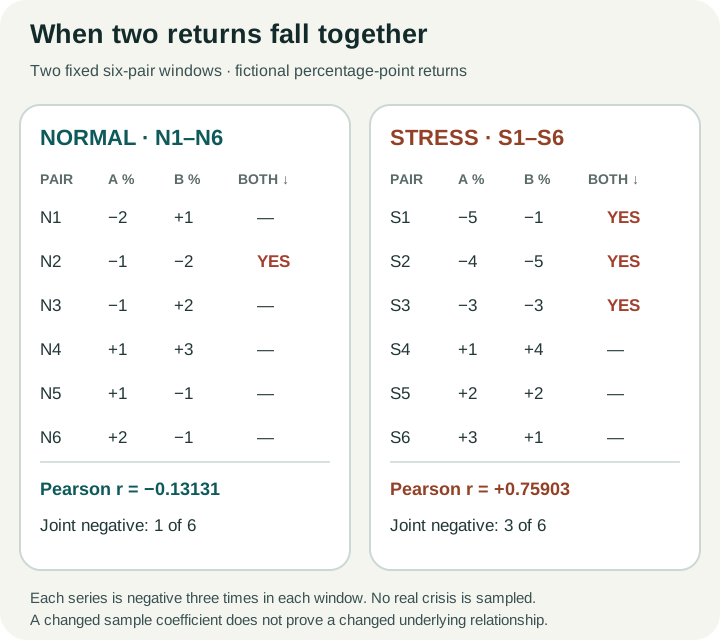
The next twelve returns are invented percentage-point observations for two hypothetical series A and B, valued at one common end-of-interval boundary. Rows N1–N6 form the first six-pair “normal” window; S1–S6 form the following six-pair “stress” window. These fixed row blocks define the calculations; “stress” is a teaching label, not a sampled historical crisis or an empirical classification. The values were hand-constructed to demonstrate one arithmetic contrast, not taken from observed returns. Both windows have complete pairs, and the twelve-row fixed-window CSV preserves every input and its joint-negative flag.
| Pair | Normal A | Normal B | Stress A | Stress B |
|---|---|---|---|---|
| 1 | −2 | +1 | −5 | −1 |
| 2 | −1 | −2 | −4 | −5 |
| 3 | −1 | +2 | −3 | −3 |
| 4 | +1 | +3 | +1 | +4 |
| 5 | +1 | −1 | +2 | +2 |
| 6 | +2 | −1 | +3 | +1 |
Within the normal window, mean A = 0 and mean B = 1/3. The centered cross-product sum is −2, so sample covariance is −2 ÷ 5 = −0.4 squared percentage points and Pearson r is −0.13131 after rounding. In the separate stress window, means are −1 and −1/3; the centered cross-product sum is 43, giving covariance 43 ÷ 5 = 8.6 squared percentage points and Pearson r approximately +0.75903. Use each window's own means and the same six complete pairs; concatenating the blocks would answer a different question.
A and B each have exactly three negative returns in each six-row window. Yet both are negative together on only N2 (1 of 6) in the first window and on S1, S2 and S3 (3 of 6) in the second. The co-loss count adds information that a single correlation hides; it is a count in a handcrafted sample, not an estimated probability. Return magnitudes and distributions differ as well, so equal per-series negative counts do not isolate a causal explanation.
For an actual comparison, predefine the calendar or event rule, interval, return basis, currency, fees, missing-value policy and minimum sample size. Report each window's observation count, return and volatility distribution, correlation and joint-loss count, then test whether the result survives reasonable alternative windows. A six-pair illustration is far too small for a stable risk conclusion; a raw correlation change does not prove a structural shift. If the series represent source and follower accounts, reconcile their exposure and deal records separately before interpreting the return pattern as copying behavior. This example supplies neither an allocation recommendation nor a product performance measurement.
Download the inputs and a blank review template
Download the synthetic inputs, the pairwise counterexample and the blank review template. The template records valuation basis, interval, timestamps, cash-flow and fee treatment, missingness rule, sample range, per-cell counts, covariance units, coefficients, source reference and unresolved limitations. It is a manual research record, not an account connection or a TradeCopier export format.
For an independent software calculation, retain the four complete rows as observations and the three columns as variables. NumPy's covariance reference documents its row/column convention and divisor control: for that layout, use rowvar=False, ddof=1. The download's numeric values are already percentage-point returns; do not compute changes of those returns or fill the empty cells with zero.
State what the matrix cannot establish
A constant series has zero standard deviation, so Pearson correlation with it is undefined. Fewer than two complete observations cannot support the sample covariance divisor. Duplicate timestamps, inconsistent intervals and unavailable valuations require explicit resolution, not silent averaging or replacement.
Zero correlation also does not prove independence. With A = −1, 0, 1 and C = A² = 1, 0, 1, C is fully determined by A, yet their paired covariance and Pearson correlation are zero. Linear association misses this nonlinear dependence.
Four invented observations demonstrate arithmetic only. For real records, disclose sample length, period, missing observations and changes in exposure or valuation method. A historical coefficient does not guarantee diversification during stress, cancellation of stop losses or matching fills between copied accounts. Retain individual exceptions and compare the underlying account events before making an operational conclusion.
Questions and answers
Why do three-row and five-row rolling correlations differ?
They include different paired observations. In the fictional Day 6 example, the three-row centered cross-product is zero while the five-row correlation is about +0.83205. State each window's boundaries and valid pair count before comparing coefficients.
When is a rolling Pearson correlation unavailable?
This example requires every paired return in its stated three- or five-row contiguous window. Early rows and the row with a missing B return have no coefficient; zero is reserved for a computed zero. A constant series also makes Pearson correlation undefined.
What is the difference between correlation and covariance?
Covariance measures joint variation in the product of the input units. Pearson correlation divides by both standard deviations, making it dimensionless. Both require aligned observations and a declared data policy.
Why does covariance change when percentages become decimals?
Each input is divided by 100, so covariance is divided by 10,000. Pearson correlation remains the same because the standard deviations scale with the inputs.
Should missing returns be entered as zero?
No. An unavailable valuation is not an observed zero return. Preserve missing values, declare the exclusion or estimation rule and report the sample used for every cell.
Why can pairwise deletion create an invalid correlation matrix?
Different cells can use incompatible samples. Every coefficient may lie between minus one and one while the assembled matrix has a negative eigenvalue and cannot represent a joint covariance of standardized variables.
How is portfolio variance calculated from covariance?
For a fixed linear combination of aligned returns, it is w transpose times the covariance matrix times w. Use compatible return units and weights, include both symmetric cross terms and reconcile with the directly calculated weighted-return series.
Is a singular covariance matrix automatically incorrect?
No. Exact linear dependence between columns can make a valid common-sample covariance matrix singular and positive semidefinite. A negative eigenvalue beyond numerical tolerance is a different issue.
Does zero correlation mean two trading series are independent?
No. Pearson correlation measures linear association. Nonlinear dependence and joint extreme outcomes can remain even when a sample correlation is zero.
Are the downloads real account results or an allocation recommendation?
No. The worked inputs are synthetic arithmetic fixtures and the template is a blank manual review record. They do not establish strategy performance, a suitable allocation or TradeCopier execution fidelity.
Do correlations always rise during a market crisis?
No. Asset pair, event, return basis and sampling rule matter. An unadjusted coefficient can also change because volatility changed, without proving a new linkage. The fictional two-window calculation illustrates a possible sample contrast, not a universal market result.
Can two return series lose together more often even if each has the same number of loss days?
Yes. In the invented six-pair windows each series has three negative observations in both blocks, but joint-negative pairs increase from one to three. That count is descriptive for twelve selected teaching rows, not a probability or forecast.
Sources and further checks
Use the current source for your exact instrument, account and platform. Referencing a general specification does not establish support for every TradeCopier workflow.
- Pandas: fixed rolling windows and minimum periods · Checked September 24, 2026
- Pandas: rolling Pearson correlation and complete pairs · Checked September 24, 2026
- NIST: Mean Vector and Covariance Matrix · Checked September 22, 2026
- R statistics: Correlation, Variance and Covariance · Checked September 22, 2026
- NumPy: covariance matrix and observation convention · Checked September 22, 2026
- NBER: International Asset Allocation with Time-Varying Correlations · Checked September 24, 2026
- NBER: No Contagion, Only Interdependence · Checked September 24, 2026
- BIS: Evaluating Changes in Correlations During High Volatility · Checked September 24, 2026
- IMF: Stock-Bond Diversification Offers Less Protection From Market Selloffs · Checked September 24, 2026
Found an error? Send a correction with this page's address and a primary source. See our editorial standards for how we handle examples, claims and revisions.