guide · Risk & sizing
Risk of Ruin in Trading: Define the Barrier Before the Formula
Risk of ruin is the probability, under a specified model, of reaching a defined failure boundary. In trading, that boundary might be a minimum operating balance or a drawdown limit rather than zero. A meaningful estimate needs a time horizon, sizing rule and assumptions about outcomes.
Key points
- Define operational failure before choosing a formula.
- A fixed-stake random walk does not describe all trading accounts.
- Fractional sizing changes the path but cannot remove gaps, minimum order sizes or model uncertainty.
Risk-of-ruin and loss-run scenarios
Loading the browser tool. The formulas, worked examples, sources and limitations remain available below.
Scope and assumptions
- The boundary model assumes independent trials, constant win probability, equal one-unit gains and losses, fixed absorbing boundaries and no costs. The separate loss-run model observes all N independent trials without account stopping rules. All examples are hypothetical; probabilities are conditional on the supplied models.
“Ruin” needs an operational definition
A trader can be unable to continue long before an account reaches zero. The balance may fall below a broker’s required margin, a contractual loss limit may be breached, or the smallest permitted position may become too large for the remaining risk budget. Calling all of these situations “risk of ruin” without defining the boundary makes the resulting percentage ambiguous.
Write the failure event as a test that can be applied to a path. For example: equity below a fixed $8,000 floor at any observation during the next 100 trades. That differs from ending below $8,000 after trade 100, because an account might cross the floor earlier and later recover. It also differs from a 20% trailing drawdown from a changing equity high.
The observation schedule is part of that definition. Suppose equity falls to $7,900 while a position is open and recovers to $8,100 when it closes. A model using only closed-trade balances misses the earlier crossing of an $8,000 equity floor. Use sufficiently detailed valuations for the rule being tested, or state that the study cannot detect intratrade breaches. Specify the price used to mark open positions and the timing of charges. A modeled valuation is also not a guarantee that liquidation could execute at that price.
The classic mathematical starting point is the gambler’s ruin model, discussed in MIT’s Mathematics for Computer Science textbook, chapter 20. It is useful for learning how boundaries and repeated trials interact. Applying it to a real trading account requires assumptions that often do not hold.
The fixed-stake model
Imagine a simplified account measured in equal units. It begins with i units, gains one unit with probability p and loses one with probability q = 1 − p. Trials are independent, probabilities stay constant, and the process stops at zero or at an upper target B. There are no commissions, gaps, variable payoffs or deposits.
For a fair process where p = 0.5, the probability of reaching zero before the upper target is 1 − i/B. Starting with 10 units and stopping at either zero or 20 gives a 50% chance of hitting zero first. This is an eventual boundary-hitting probability in that toy model, not a statement about what will happen in the next ten trades.
When p differs from 0.5, let r = q/p. For 0 < p < 1, the probability of hitting zero before B is (ri − rB) / (1 − rB). The expression is sensitive to p and the boundaries. A historical win rate cannot simply be treated as a known, unchanging p, especially when winning and losing amounts are unequal.
Explore a finite horizon with an absorbing boundary
The interactive explorer above adds a stopping horizon to the equal-stake model. Enter starting units i (labeled S in the controls), upper boundary B, maximum trials N and assumed win probability p. Each active step changes the state by exactly +1 or −1 unit. Reaching zero or B ends that path immediately; later hypothetical trades are not taken. The inputs are abstract units, not dollars, a risk percentage or a broker account rule.
The three outputs answer mutually exclusive questions: hit the lower boundary by N, hit the upper boundary by N, or reach neither within N. They sum to 100% before display rounding. “Neither” is unresolved at this horizon, not permanently safe. At N = 0, an interior starting state has 100% unresolved probability because no trial has occurred.
Here is an original four-step example with i = 2, B = 4 and p = 50%. Every active trial is an independent, equal-probability gain or loss.
| Maximum trials | Lower boundary reached | Upper boundary reached | Neither reached |
|---|---|---|---|
| 0 | 0% | 0% | 100% |
| 2 | 25% | 25% | 50% |
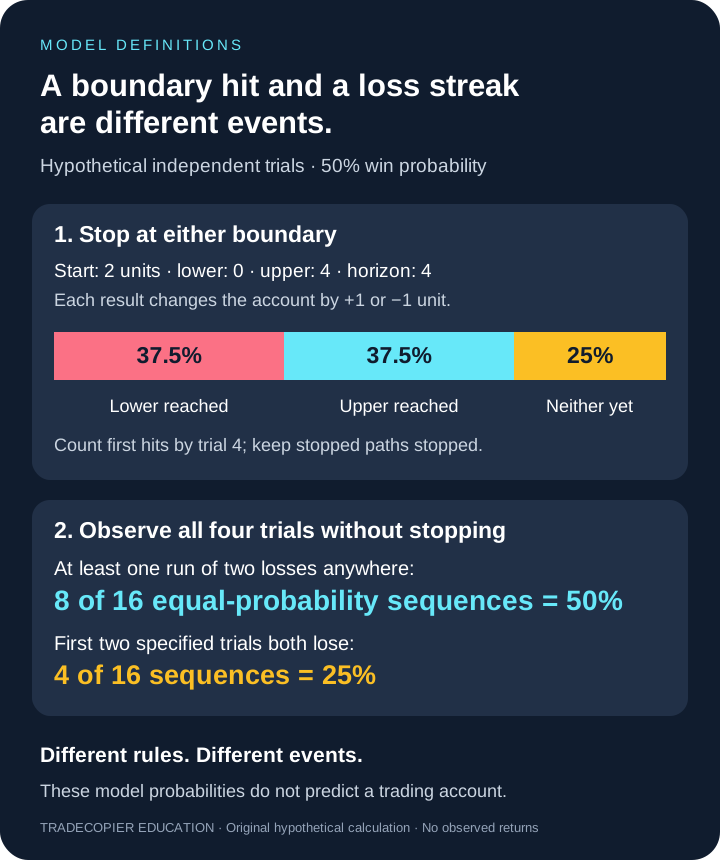
| 4 | 37.5% | 37.5% | 25% |
At two trials, loss–loss reaches zero and win–win reaches four. The two mixed sequences return to two. Repeating that calculation for the unresolved paths adds 12.5 percentage points to each boundary by trial four. The eventual lower-boundary probability is 50% in this fair symmetric example; 37.5% is the different answer for the four-trial horizon.
The tool calculates probability states directly. It starts with all mass at i; each active state sends p of its mass one unit up and 1 − p one unit down. Boundary mass stays absorbed. This deterministic recurrence has no random simulation seed or sampling noise. It still uses finite-precision arithmetic, and its exactness within a toy model does not establish that the model describes an account.
The sensitivity rows change p by five percentage points in each direction, clipped to the 0–100% input range. These are alternative assumptions, not confidence bounds or an estimate of the true win rate. Fractional stakes, unequal wins and losses, costs, dependence, changing boundaries and intratrade marks need other models.
Why a trading win rate is insufficient
Suppose two hypothetical systems each win 60% of trades. One wins $100 and loses $100; another wins $20 and loses $200. The frequency of winners is identical, but their outcome distributions are very different. A calculator accepting only win rate and account size has omitted essential information unless it explicitly assumes equal gain and loss units.
Use expectancy and win-rate analysis to understand the average outcome, then examine the full loss distribution. Costs, clustered losses and occasional outsized moves affect the path to a boundary. A profitable historical average does not imply a negligible chance of crossing a loss limit.
Estimation uncertainty also matters. An observed win rate of 60% from a short sample does not establish a 60% future probability. Repeating a simulation with a less favorable assumed win probability is a sensitivity exercise. It reveals dependence on an input, without proving which input will match the future.
Fixed amount versus a fraction of remaining equity
With a fixed $100 loss per trade, ten consecutive losses remove $1,000 regardless of the starting account. With an idealized loss of 1% of remaining equity each time, equity after ten losses is initial equity multiplied by 0.9910. From $10,000, that leaves approximately $9,043.82, a decline of about 9.56%.
At a 5% fractional loss, the same ten-loss sequence leaves $10,000 × 0.9510, approximately $5,987.37, a decline of about 40.13%. These are deterministic illustrations of a supplied sequence, not recommendations for either risk fraction and not probabilities of that sequence occurring.
| Illustrative sizing rule | Equity after ten stated losses | Decline from $10,000 |
|---|---|---|
| Fixed $100 each | $9,000.00 | 10.00% |
| 1% of remaining equity | $9,043.82 | 9.56% |
| 5% of remaining equity | $5,987.37 | 40.13% |
An ideal fractional model with losses strictly below 100% never reaches exactly zero in a finite number of steps. That mathematical property does not make operational ruin impossible. The account can cross a meaningful floor, lose the ability to place a minimum order, or experience a loss larger than the model permits.
Consecutive losses: a specified block versus a run anywhere
The second calculator asks about sequences, not account balances. Under independent trials with constant loss probability q = 1 − p, the probability that one specified block of k trials consists entirely of losses is qk. That does not answer whether at least one such run appears anywhere among N trials. Potential windows overlap: a three-loss sequence contains two overlapping two-loss windows, so adding their probabilities double-counts paths.
MIT’s probability exercise on runs, problem 6 illustrates the distinction between a sequence and a long run within it. Our calculator uses an original deterministic state recurrence rather than that exercise’s simulation method. Before a run has occurred, it tracks the number of trailing losses: a win resets that number to zero, a loss increases it by one, and reaching k records the event once.
With p = 50%, k = 2 and N = 4, a specified pair is two losses with probability 25%. A run of at least two losses anywhere in the four trials has probability 50%: eight of the sixteen equally likely sequences contain a qualifying run. This second model observes all four trials regardless of either account boundary. For example, win–win–loss–loss contains a loss run, but the boundary model beginning at two stops at four after the first two wins. Its later losses are never taken.
If k exceeds N, a within-horizon run is impossible. The separate hypothetical k-trial block still has probability qk, but that block does not fit inside the chosen horizon. With no trials, there is no positive-length run. If p = 100%, losses cannot occur in the model; if p = 0%, the run occurs when N is at least k. Larger permitted horizons are calculated with the same recurrence, not by assuming non-overlapping windows.
A displayed tiny value or numeric underflow must not be read as a real-world guarantee of zero risk. The tool distinguishes impossible events under the supplied model from positive probabilities below display or numeric precision. Neither model estimates dependence between copied accounts or validates a historical win rate. The CFTC’s discussion of hypothetical trading results is a useful reminder that modeled outcomes do not establish actual trading performance.
A loss floor and a trailing drawdown are different barriers
Consider an account beginning at $10,000 with a fixed $8,000 floor. It rises to $12,000 and then falls to $9,500. The fixed floor has not been crossed. A 20% trailing drawdown boundary from the new high is $9,600, so the same path has crossed that boundary. A model using only starting balance would miss the difference.
Daily reset times can create another distinction. A daily limit may use start-of-day balance, equity at a particular time, or another contractual definition. Model the actual documented rule, including treatment of open positions. Do not infer it from a familiar percentage or from the name of a platform setting.
The drawdown recovery calculator answers the separate arithmetic question of the gain required after a loss. It does not estimate a ruin probability. Keeping these tools’ purposes separate avoids presenting a simple percentage calculation as a forecast.
How to build a more useful scenario study
- Specify starting equity, currency, failure boundary and evaluation horizon.
- Choose a sizing rule with minimum size, rounding and exposure constraints.
- Define net outcomes using a documented historical sample or an explicit hypothetical distribution.
- Model path-dependent rules, including trailing highs and simultaneous positions.
- Count paths that breach the boundary at any relevant observation, not just those ending below it.
- Repeat with alternative cost, dependence and extreme-loss assumptions.
A Monte Carlo study can support this exercise, but its reported breach rate is conditional on its model. Randomly shuffling old trades does not create a new kind of loss that was absent from the sample. Sampling trades independently may also erase the clustering that made historical drawdowns difficult.
Do not confuse a stop setting with a guaranteed loss cap
A planned stop distance is an input to sizing, while the realized exit depends on execution. Gaps, market conditions, rejected requests and connection failures can create different outcomes. A useful stress case asks what happens if several accounts encounter the same adverse event before all exits complete.
Adding copied accounts does not automatically diversify that event. If they follow the same source position, their losses can be linked. Review combined exposure and the copy lot ratio with each account’s contract specifications. Equal lot numbers do not always mean equal monetary exposure.
TradeCopier’s equity protection controls belong to the operational process; they do not certify a modeled ruin percentage. Test the configured behavior in an appropriate demo environment and reconcile what the broker actually reports. Keep emergency procedures and account permissions explicit.
Report uncertainty instead of a comforting single number
A useful report states the sample dates, number of trades, boundary definition, horizon, sizing convention and cost assumptions. It shows how results change when a key assumption changes. It also lists exclusions, such as financing, illiquid exits or simultaneous positions that the model could not represent.
If a model reports no failures in a finite set of simulated paths, write “no modeled breaches in this run,” not “zero risk.” The absence of an observed event is different from mathematical impossibility. Preserve the model configuration and source data so another reviewer can reproduce the result and challenge its assumptions.
Questions and answers
Does risk of ruin always mean losing the entire account?
No. For an operational trading analysis it can mean reaching a defined minimum balance, drawdown threshold or other failure condition. The boundary must be stated explicitly.
Can I calculate risk of ruin from win rate alone?
Not for a general trading strategy. Payoff sizes, costs, position sizing, dependence, the failure boundary and time horizon also matter. Simple formulas rely on restrictive assumptions.
Does fractional position sizing eliminate ruin?
No. An ideal model may never reach exact zero, yet the account can cross an operational floor. Real losses, minimum order sizes, gaps and execution constraints can also violate the model.
Why do the finite-horizon results differ from the gambler’s ruin formula?
The finite-horizon tool counts boundary hits only through N trials and reports unresolved paths separately. The eventual formula asks which boundary is reached first without that deadline. Both require the equal-stake independent-trial model.
Is this risk-of-ruin explorer a Monte Carlo simulation?
No. It propagates probability through a finite set of states deterministically. There is no random sample or simulation seed, but numeric precision and restrictive model assumptions still limit interpretation.
Is the probability of consecutive losses simply q to the power k?
That is the probability for one specified block of k independent trials, where q is the constant loss probability. At least one run anywhere within N trials is a different event because its possible windows overlap.
Does the consecutive-loss calculator stop at the account boundary?
No. It observes all N hypothetical trials. The separate account-boundary model stops immediately at zero or the upper boundary, so its probability is not interchangeable with the loss-run result.
Are the sensitivity rows confidence intervals or a zero-risk guarantee?
Neither. They show alternative assumed win probabilities five percentage points above and below the input, clipped to 0–100%. Very small or rounded probabilities do not establish zero real-world risk.
Sources and further checks
Use the current source for your exact instrument, account and platform. Referencing a general specification does not establish support for every TradeCopier workflow.
- MIT OpenCourseWare: Mathematics for Computer Science, chapter 20 · Checked September 22, 2026
- CFTC: Risks and limitations of trading-system performance claims · Checked September 22, 2026
- MIT OpenCourseWare: 18.05 Problem Set 2, problem 6 on runs · Checked September 22, 2026
Found an error? Send a correction with this page's address and a primary source. See our editorial standards for how we handle examples, claims and revisions.